TAG
#playtesting
0 reviews · 6 essays
Related essays
Guo et al.: humans drifted off the greedy move within about ten games; self-evolving AI did not — Fukai Reads
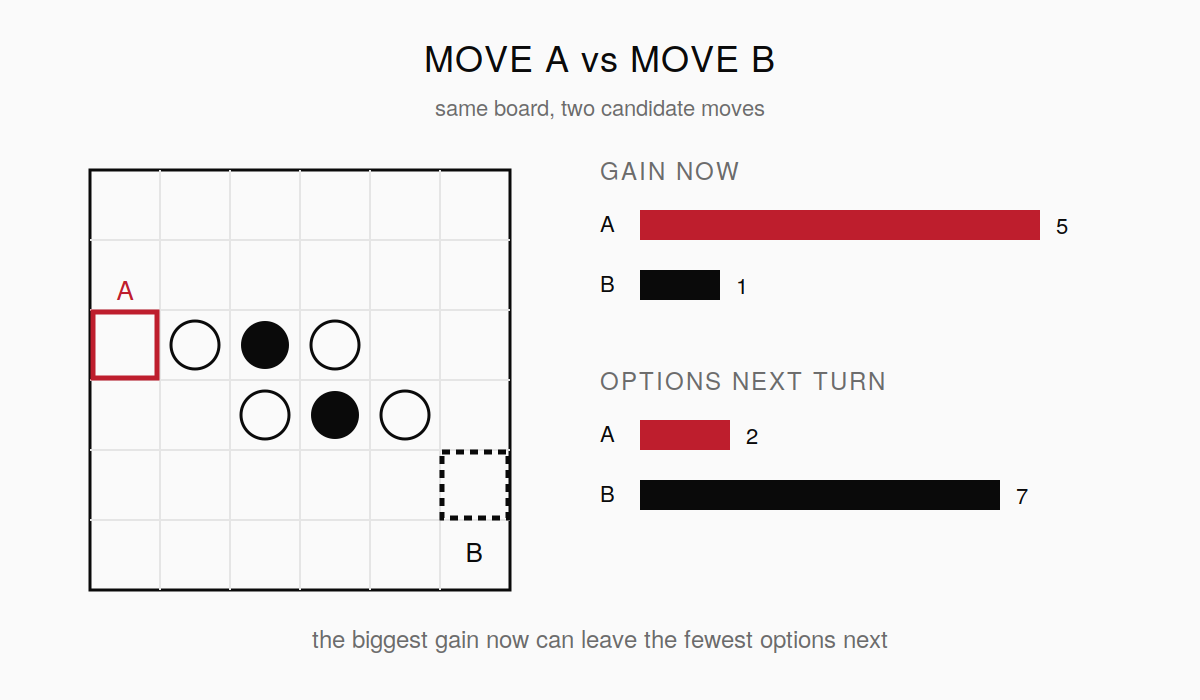
A preprint by Yingying Guo and four co-authors (arXiv:2608.07490, not peer-reviewed). They propose a way to measure how repeated play changes the way humans and language agents choose moves. Thirty-two students played 709 games across three board games, and four self-evolving language agents were run through the same metric space. Humans mostly shifted from the locally greedy move toward more global play: on the game-specific behavioral metrics, 11 of 12, 10 of 11 and 8 of 9 participants improved. The agents' gains were short-lived. The authors write that the central limitation is not the absence of reflection but the failure to convert reflection into reusable changes in behavior.
Hu et al.: We Judge Others' Satisfaction Without Counting Their Options — Fukai Reads
A peer-reviewed paper by Beidi Hu, Alice Moon and Eric VanEpps in Psychological Science (January 2026). Across six preregistered experiments with 10,092 participants, people factored choice set size into their own satisfaction but barely factored it into predictions of someone else's. Three things shrink the neglect: showing the different set sizes side by side, asking for a ranking, and restating the number of options. It bears directly on how we read playtests and pick rates.
Huang et al.: Letting an AI Play the Generated Game, Then Fix It — Fukai Reads
A game-generation paper by Yixu Huang and colleagues (Fudan University, Xiaohongshu and others). Play2Code puts a screen-driving GUI agent into the generation loop as a playtester, evaluated on PlaytestArena, a new environment of 200 tasks and 1,548 rubric criteria. Averaged over three backbones, rubric pass-rate goes from 29.7% for single-pass generation and 52.2% for a code-inspection-only pipeline to 66.8%.
The strongest player is not the best tester: a paradox from a framework for measuring game difficulty with LLMs
One piece today. I read, in the original English, "LLMs May Not Be Human-Level Players, But They Can Be Testers: Measuring Game Difficulty with LLM Agents" by Chang Xiao (Adobe Research) and Brenda Z. Yang (Columbia University) (arXiv:2410.02829). It asks whether off-the-shelf LLMs can be used to measure game difficulty by letting them play a game and treating their performance as a difficulty proxy, tested on Wordle (a word puzzle) and Slay the Spire (a deck-building roguelike). The central finding is a paradox: LLMs play worse than the average human, yet the relative difficulty of challenges they struggle with correlates strongly with human data. Moreover, a near-optimal, information-theoretic Wordle solver that beats humans on move count showed almost no correlation with human-perceived difficulty. In other words, the entity that solves best is not the best difficulty tester. A thought-provoking read for anyone thinking about how to validate a difficulty curve.
Puzzles Made to Show Off a System, Not to Stump You — Patrick Traynor on System-Centric Design in Patrick's Parabox (GDC 2024)
One article today: the official slides from Patrick Traynor's GDC 2024 talk, "System-Centric Puzzle Design in Patrick's Parabox." His premise is inverted: "the purpose of the system is not to make cool puzzles. The purpose of the puzzles is to showcase this cool system." So difficulty is tuned to communicate, not to challenge — puzzles simplified as much as possible while still conveying their idea. He covers smoothing the learning curve (insert, modify, delete, reorder, optionalize), ~15 full-game playtests recorded with narration, an idea-finding method of "find an interaction and force it," and a heuristic for a good puzzle system: how many puzzles you can make in it. 364 shipped puzzles, 600+ unused drafts. A 2024 talk, but worth reading now for how it reframes a core design assumption.
Li et al.: AutoBG, an AI that supports board game design end-to-end from ideation to finish — Fukai Reads
A paper (arXiv preprint) by Zizhen Li et al. on AutoBG, a board game design assistant that covers the whole workflow—ideation, rulebook generation, and individualized feedback—via Verifier-Gated Iteration that splits the generator from the critic; the critic, BG-Critic, is reported to outperform GPT-5.4 on diagnostic quality.