TAG
#llm
0 reviews · 28 essays
Related essays
Guo et al.: humans drifted off the greedy move within about ten games; self-evolving AI did not — Fukai Reads
A preprint by Yingying Guo and four co-authors (arXiv:2608.07490, not peer-reviewed). They propose a way to measure how repeated play changes the way humans and language agents choose moves. Thirty-two students played 709 games across three board games, and four self-evolving language agents were run through the same metric space. Humans mostly shifted from the locally greedy move toward more global play: on the game-specific behavioral metrics, 11 of 12, 10 of 11 and 8 of 9 participants improved. The agents' gains were short-lived. The authors write that the central limitation is not the absence of reflection but the failure to convert reflection into reusable changes in behavior.
Li et al.: the AI that showed up uninvited was closed by five players out of ten — Fukai Reads
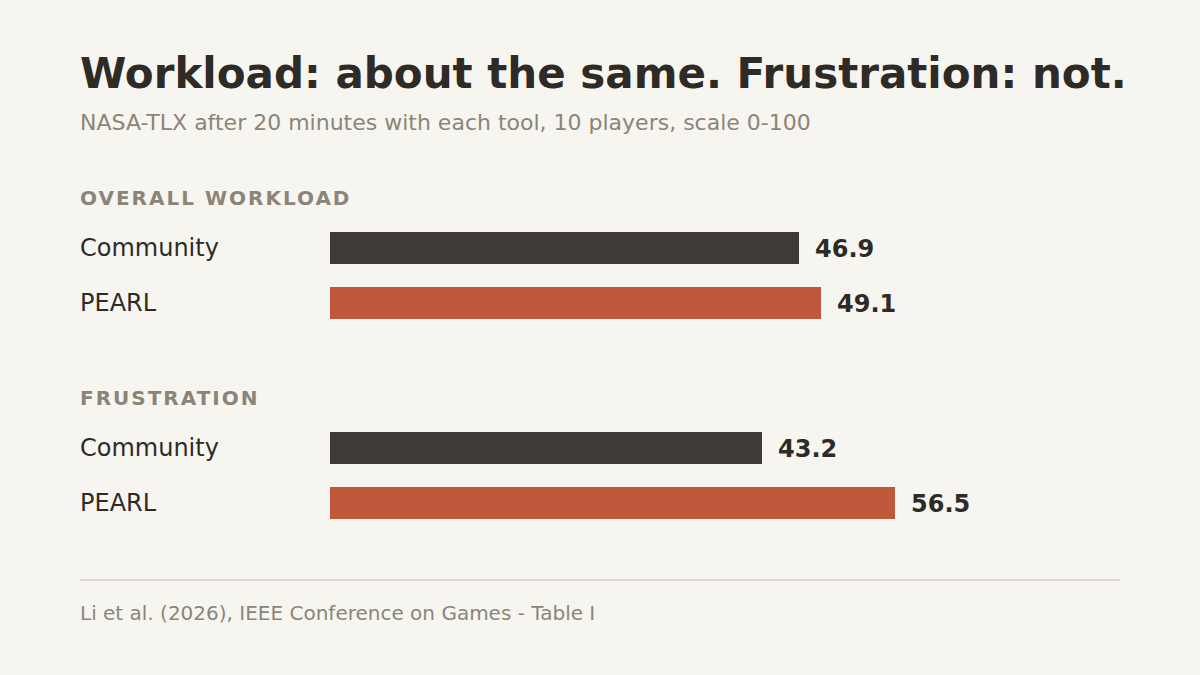
A peer-reviewed paper by Jiahong Li and eight co-authors (accepted to the 2026 IEEE Conference on Games, arXiv:2609.13718). They built PEARL, an AI support agent that retrieves expert-annotated move explanations and structurally similar peer boards, into Parallel, a puzzle game for learning parallel programming, and evaluated it with ten players. Participants rated the existing visualization tool more useful, and at least five minimized or abandoned the AI during play. Frustration scored 43.2 against 56.5. The authors conclude that what players rejected was not the content of the help but its unsolicited delivery, and ask of their own system: are we building Clippy?
Siper et al.: Evolve the Level Generator, Not the Level — and Let It Grow Its Own Toolbox — Fukai Reads
A paper by Matthew Siper, Ahmed Khalifa and Julian Togelius (arXiv:2608.17947, accepted at IEEE Conference on Games 2026). Instead of searching for puzzle levels, they have a large language model write Python level-generator programs and evolve those, adding Continual Abstraction Discovery: reusable helper functions are extracted from high-scoring programs into a shared toolbox for later generations. Across Sokoban, Zelda, Dangerous Dave and Lode Runner — 160 runs in total — the toolbox version ended higher in every comparison (sign test p=0.008).
Elshamy et al.: Read the player's skill, then redraw the level itself — Fukai Reads
A Scientific Reports paper from Elshamy and colleagues at E-JUST on inferring player skill and rewriting the terrain of the level itself. Where conventional dynamic difficulty adjustment tunes enemy health and item drops, this pipeline rearranges floors, gaps and enemies in place. Skill classification reached 97.82% accuracy; 74.1% of rewritten levels remained completable.
O'Neill et al.: A Board Where Nothing Makes You Keep Your Word — Fukai Reads
A paper from UC Berkeley introducing C2C, a four-player conquest game built to measure negotiation and betrayal. On a board with no mechanism at all to enforce agreements, language models and humans played over 1,100 games — and humans turned out to make far fewer promises than the AI agents did.
Geheeb et al.: Let an LLM Poke at Your Game Design Pillars — Fukai Reads
A paper on game design pillars and LLMs by Julian Geheeb and colleagues at the Technical University of Munich. Pillars are heavily used in industry but almost unexamined academically; the paper gives them a formal definition and quality criteria, then hands structural checking, contradiction detection and feature evaluation to an LLM in a prototype called SPINE. A 42-hour game jam and interviews with four developers produce a consistent picture: useful at the moment of putting a pillar into words, thinning with each rewrite iteration, and unable to recognise deliberate juxtaposition when flagging contradictions. Peer-reviewed at FDG '26.
Chen: Reconstruct the Persistent World First, Then Build Something Playable — Fukai Reads
A narrative-to-game paper by Yi-Chun Chen. Before generating scenes or gameplay individually, it makes explicit reconstruction of a persistent world — entities, locations, relationships, evolving state — the central objective, maintained as one computational object shared across the pipeline. The prototype builds the world with GPT-5-mini plus constrained world completion and realises it as playable tile-based PyGame environments. An arXiv preprint offering qualitative feasibility across three cases, with no quantitative evaluation.
Huang et al.: Letting an AI Play the Generated Game, Then Fix It — Fukai Reads
A game-generation paper by Yixu Huang and colleagues (Fudan University, Xiaohongshu and others). Play2Code puts a screen-driving GUI agent into the generation loop as a playtester, evaluated on PlaytestArena, a new environment of 200 tasks and 1,548 rubric criteria. Averaged over three backbones, rubric pass-rate goes from 29.7% for single-pass generation and 52.2% for a code-inspection-only pipeline to 66.8%.
Wu et al.: Rebuilding a Case Report Into a Chain of Decisions — Fukai Reads
A medical-education gamification paper by Qian Wu and colleagues (CUHK and others). MedGame is a dual-engine framework that converts static case reports into a three-level Act / Scene / Decision Node script and then into a dependency graph of multimodal generation tasks. Fine-tuning on a 5,000-case benchmark lifts structural validity from 79.4% to 99.1%, while medical accuracy plateaus around 7 out of 10.
Wang et al.: Making a Puzzle Solver the Teacher for Every Single Move — Fukai Reads
A game-AI paper by Yu Wang and colleagues. Where long-horizon puzzles reward only the final win, they convert the drop in a solver's remaining-distance-to-goal into a per-move score and mix it into training. Averaged over Sokoban, Minesweeper and Rush Hour, success rises from 16.6% to 62.1%, and on unseen difficulty from 5.9% to 28.4%. Querying the solver costs about 73 parts per million of training wall clock.
Zhou et al.: The Verifier is the Curriculum — Training Game Generation on a Launch Check Alone — Fukai Reads
A game-generation paper by Chenyu Zhou and colleagues. Starting from a diagnosis that the learned judge is gameable, they gate self-distillation on a single binary signal — does the generated Godot project launch cleanly — and over three rounds lift clean generation on four unseen families from 8.8% to 42.2%, with best-of-16 coverage going 18/25 to 25/25. Loosen the gate and the gain disappears.
Teo et al.: AI Assistants Overassist — Int-Bench Measures Intervention in Problem-Solving — Fukai Reads
Teo et al. on LLM intervention behavior. Using Int-Bench, a simulated setting, they measure when and how much AI assistants help during problem-solving, finding AI intervenes earlier and more often than humans, tends to leak the answer, and does not improve transfer. A useful read for puzzle hint design.
Johnson et al.: What Changes in a Game When You Build an LLM Into It — Fukai Reads
A qualitative study by Johnson and colleagues at the University of Calgary on developing two games with an LLM embedded in their structure. Reading developer reflections, it analyzes how embedding an LLM as a component (not decoration) changes gameplay, playability, and player experience. Variability and personalization increase, but new burdens of correctness, difficulty calibration, and coherence emerge, with schema enforcement and validation as the keys.
Zeng et al.: Automating Game Balancing with LLM-vs-LLM Self-Play — Fukai Reads
A paper by Zeng et al. on automated game balancing. It tackles balancing asymmetric strategy games by using multi-agent LLM self-play as an evaluator and Bayesian optimization to search rule parameters, reporting convergence to near-0% win-rate gaps on their own game, CivMini.
Waugh: Measuring AI's Reasoning with Sudoku and Slitherlink — Fukai Reads
A paper (arXiv preprint) by Justin Waugh of Approximate Labs on Pencil Puzzle Bench, a benchmark that measures LLM reasoning with pencil puzzles. From 62,231 puzzles across 94 types it selects 300, and its core is that a machine can verify every move against the rules; 51 models were evaluated. Even the strongest GPT-5.2 reached only 56.0% in agentic mode, with about half unsolved.
Triebel et al.: Does AI Have Both a Head and a Hand on a Classic Physics Puzzle? — Fukai Reads
A paper by Triebel et al. evaluating VLMs on the classic physics puzzle The Incredible Machine 2. Using VLATIM, a five-stage benchmark, it asks whether screen-operating AI can solve problems like humans; the cleverer large models can plan but cannot click precisely, and no model solved even one puzzle to completion.
Xu et al.: When Generative AI Becomes the Heart of Play — Fukai Reads the AI-Native Games Survey
A survey (arXiv preprint) by Zhiyue Xu and five co-authors on "AI-native games," where generative AI is the core loop itself. It defines them by a counterfactual — would play collapse if the AI were removed — and classifies 53 real artifacts along two axes: game type (G) and dominant AI mechanic (N), showing a skew toward narrative genres and a thin use of AI at the rule layer.
Letting an LLM build a whole game, and an AI playtest it: ScriptDoctor and the state of automatic game design
One piece today. I read, in the original English, "ScriptDoctor: Automatic Generation of PuzzleScript Games via Large Language Models and Tree Search" by Sam Earle, Julian Togelius and colleagues (arXiv:2506.06524; a short paper submitted to the IEEE Conference on Games). They pick PuzzleScript — the description language for turn-based 2D-grid puzzle games created by increpare (Stephen Lavelle) — as a "model organism," and have an LLM generate a whole game (rules, sprites, levels), iterating on it using compiler errors and the results of a breadth-first-search player agent. Feeding in a few human-authored games as examples clearly raises quality, and reasoning models (o1, o3-mini) beat GPT-4o. But the sharpest lesson is on the failure side: the games that looked most complex were often complex only because of broken mechanics — solvable is not the same as good. A rich read for anyone thinking about automatic game design.
Mirowski et al.: From Writing a Story to Finding One — Fabula, a Writing AI Grown With the Writers' Community — Fukai Reads
A paper on Fabula, a Google DeepMind writing-support AI. Its hierarchical story planner-generator, the Drama Manager, was critically co-developed with 42 experts; it proved strong at structure but weak at style and surprise. Fukai reads it for lessons that apply directly to game interactive narrative.
The strongest player is not the best tester: a paradox from a framework for measuring game difficulty with LLMs
One piece today. I read, in the original English, "LLMs May Not Be Human-Level Players, But They Can Be Testers: Measuring Game Difficulty with LLM Agents" by Chang Xiao (Adobe Research) and Brenda Z. Yang (Columbia University) (arXiv:2410.02829). It asks whether off-the-shelf LLMs can be used to measure game difficulty by letting them play a game and treating their performance as a difficulty proxy, tested on Wordle (a word puzzle) and Slay the Spire (a deck-building roguelike). The central finding is a paradox: LLMs play worse than the average human, yet the relative difficulty of challenges they struggle with correlates strongly with human data. Moreover, a near-optimal, information-theoretic Wordle solver that beats humans on move count showed almost no correlation with human-perceived difficulty. In other words, the entity that solves best is not the best difficulty tester. A thought-provoking read for anyone thinking about how to validate a difficulty curve.
Let the LLM Handle Story and Puzzles, Let the Symbolic Layer Keep the World From Breaking — Uruguay's IVIE on Incremental, Validated Generation of Interactive Fiction (ICCC'26)
One article today: IVIE, a paper headed to ICCC'26 by a team at the Universidad de la República in Uruguay (Vaucher, Silveira, Góngora, Chiruzzo), which I read in full in the original English on arXiv. The goal is to generate complete, playable interactive-fiction (text-adventure) worlds from scratch. The trick is a division of labor: creative decisions—setting, characters, puzzle design—go to an LLM, while a symbolic layer guarantees structural facts like spatial connectivity and objective solvability. Worlds are built backwards from the objective across four stages, each with a validation gate. In the puzzle stage, obstacle and solution are placed in different locations, solutions must be discoverable through exploration, and hints disclose in three escalating levels. Tellingly, in 3 of 16 evaluated worlds players slipped past puzzles simply by claiming they had solved them—surfacing a design tug-of-war: validate too strictly and you choke creativity; too loosely and the puzzles become hollow. Not a puzzle game per se, but a paper that touches the root of design: how to make 'validation' and 'freedom' coexist.
Monti et al.: Measuring AI's Planning Power on a Single-Corridor Sokoban — Fukai Reads
A paper by Monti and colleagues on SokoBench, a benchmark that measures reasoning models' long-horizon planning with Sokoban. By lining up only single-box straight corridors and narrowing difficulty to a single axis (corridor length), it shows that even state-of-the-art reasoning models break down once more than 25-30 moves of lookahead are needed. The authors locate the cause in accumulated miscounting.
Luo et al.: Can AI Agents Build Whole Playable Games in a Real Engine? — Fukai Reads
A paper by Luo, Wang and colleagues on GameCraft-Bench, a benchmark for end-to-end game generation by coding agents. It has agents build complete playable games on Godot from natural-language specs, judged by launch, input replay, and video-based scoring across 140 tasks in 15 families. Even the strongest configuration reaches only 41.46% overall, and the authors report that agents can build mechanics but fall short of finished games with content, readability, and polish.
Li et al.: AutoBG, an AI that supports board game design end-to-end from ideation to finish — Fukai Reads
A paper (arXiv preprint) by Zizhen Li et al. on AutoBG, a board game design assistant that covers the whole workflow—ideation, rulebook generation, and individualized feedback—via Verifier-Gated Iteration that splits the generator from the critic; the critic, BG-Critic, is reported to outperform GPT-5.4 on diagnostic quality.
Nasir et al.: Evolving the Rules of Play Themselves — Fukai Reads MORTAR
A paper on automatic game design by Nasir, Togelius and colleagues. Instead of levels, MORTAR evolves game mechanics themselves using a quality-diversity algorithm paired with a large language model, judging quality by whether stronger AI agents reliably beat weaker ones. Running on GPT-4o-mini, it generates diverse, playable games and even quantifies each mechanic's contribution.
Jiang et al.: Can a Sentence Build a Playable Game? — Fukai Reads OpenGame
A paper by Yilei Jiang et al. (CUHK) on OpenGame, an agent that generates whole 2D web games from natural language. Reusable skeletons and a 'living debug protocol' curb integration errors, setting a new state of the art across 150 tasks - though puzzles remained its weakest genre.
Li et al.: Can LLMs Play and Beat 2D Games? - Fukai Reads GVGAI-LLM
A paper by Li et al. (NYU and others) proposing GVGAI-LLM, a benchmark that has language models play 118 2D games to measure reasoning and spatial grounding. Translating boards into ASCII maps and solving zero-shot, GPT-4o-mini scored 0% on 477 of 540 levels and a 10.27% overall win rate, falling short of classic search algorithms. I unpack it as problem, method, findings, use cases, and limitations.
Can AI Build a Whole Puzzle Game? ScriptDoctor and Its Generate-Playtest-Repair Loop
ScriptDoctor has a large language model write an entire puzzle game — rules, sprites, levels — then lets a compiler and a search-based agent inspect the result and demand revisions. The testbed is PuzzleScript, a language indie developers know well. I walk through the paper in five parts — problem, method, findings, where you can use it, limitations — covering why human-authored examples boost success rates, why reasoning models win, and the distance between 'solvable' and 'fun'.